I loved doing the Daily Blogroll, but Google Analytics showed almost nobody used it to read blogs. I think I was the one who used it the most, and so I’m not going to be promoting it on BlueSky and Mastodon anymore (or not much anyway). I got a lot of flack for using AI to summarize blogs. I didn’t see how what I was doing hurt anyone — not like I copied or republished content or anything, I just summarized it. Still, “AI” is a dirty word for a lot of people, and many think there is no legitimate use for the tech.
I disagree.
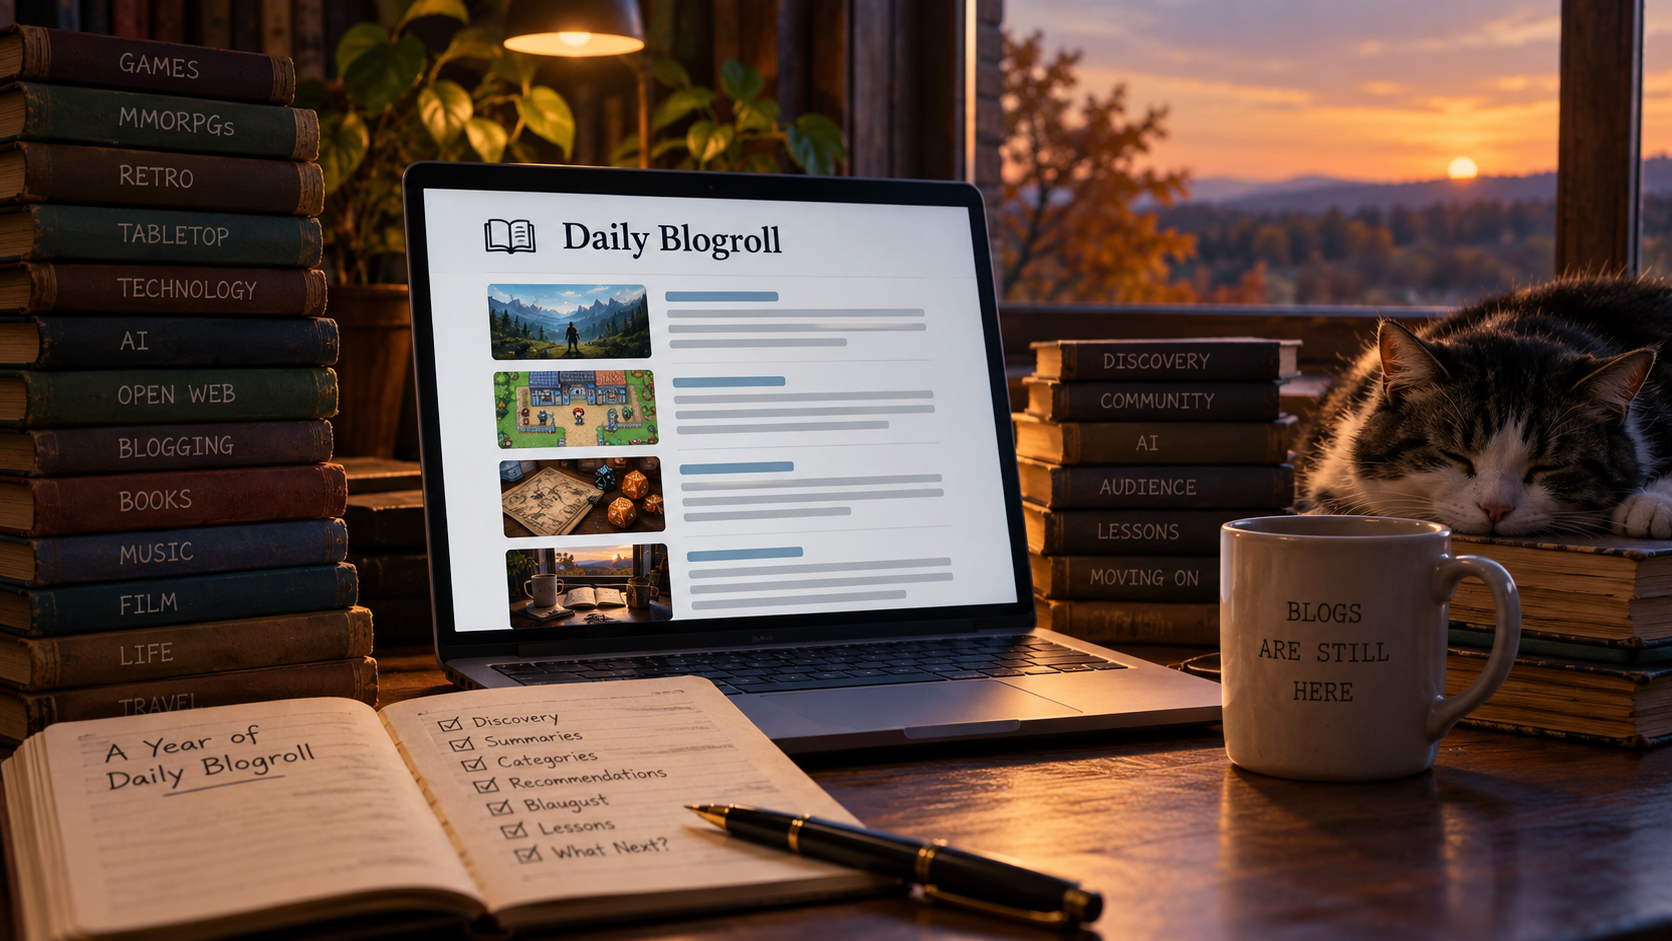
The retrospective post that follows was written by the chatbot that figured out the hashtags I used to promote each post, given the blog summaries generated by the RSS bot. I then asked it to generate a header image, so yeah, it’s all AI.
For the past year, Daily Blogroll attempted something that sounds simpler than it is: take a curated set of independent blogs, read what they published, summarize the interesting posts, and turn the result into a daily digest.
The project began as an editorial exercise. Its basic assumption was that a sufficiently careful human curator could make a sprawling personal-blog ecosystem easier to follow. The blogs were already selected for quality and fit. Daily Blogroll would perform the second stage of filtering: deciding what was worth surfacing on a particular day.
That worked, for a while.
Then the source list grew.
More blogs meant more good posts, but it also exposed the central weakness of a manually curated digest: selection does not scale in the same way discovery does. A larger source pool did not simply produce a better Daily Blogroll. It produced a more heterogeneous one, and readers increasingly encountered material that was interesting in the abstract but not necessarily interesting to them.
That problem eventually became the most useful part of the experiment.
The original value was discovery
Daily Blogroll was never a general-purpose feed reader. Its source list was intentionally narrow.
The blogs tended to be independent, personal, RSS-friendly, and written by people who had been doing this for a long time. Many were gaming blogs, but the actual subject range was much wider: MMORPGs, tabletop games, retrocomputing, game development, programming, books, films, music, photography, security, AI, personal essays, travel, retirement, and the ongoing mechanics of blogging itself.
A great many of those blogs came through Blaugust, directly or indirectly.
That mattered because Blaugust turned out to be more than a source of names. It was a useful quality filter. People who voluntarily commit to writing regularly for an entire month tend to be people who actually enjoy maintaining a blog. Many continue writing long after August ends. That produces a very different population from one assembled through search engines, social-media recommendations, or topical newsletters.
The result was a small but remarkably durable blogging ecosystem.
One of the strongest lessons of the project was that there is still a large amount of worthwhile personal writing on the open web. The problem is not that nobody blogs anymore. The problem is that blogs are poorly connected to one another, unevenly indexed, and difficult to discover unless somebody is already inside the ecosystem.
Daily Blogroll was useful partly because it supplied those missing connections.
The ecosystem was more coherent than it first appeared
After enough months, recurring patterns became visible.
The MMORPG blogs, for example, were rarely about conquest in the old sense. They were increasingly about inhabiting games: housing, crafting, economies, alts, routines, server communities, nostalgia, and the small decisions that make persistent worlds feel lived in.
Retro gaming was also less about nostalgia than expected. Many posts were preservation work in disguise: translations, ROM patches, old hardware, forgotten ports, fan projects, archival research, and attempts to explain why an old design still matters.
AI changed during the life of the project as well.
Early AI posts often treated generative systems as a novelty or a tool. Later posts were much more likely to discuss AI as infrastructure: coding assistants, scraping, bot traffic, search degradation, surveillance, publishing economics, spam, security research, and the changing cost of producing low-quality content at scale.
Blogging itself remained one of the most persistent subjects.
Writers discussed RSS, WordPress, Hugo, static-site generators, webmentions, IndieWeb tools, hosting, comments, site migrations, analytics, spam, and the simple question of why anyone still bothers maintaining an independent site.
This became one of the project’s more encouraging findings. The open web is not merely a place where people publish material about other subjects. For many of these writers, the web itself remains a subject worth thinking about.
Blaugust was both a stress test and a demonstration
Blaugust put unusual pressure on the project.
Posting frequency rose sharply. The source pool produced more material, and many bloggers who usually published occasionally began posting daily or nearly daily.
That created an obvious volume problem, but the more interesting effect was qualitative.
During Blaugust, blogging became unusually self-referential. There were posts about maintaining streaks, finding topics, burnout, community, discovery, comments, readership, why people blog, and what happens when the month ends.
In 2026, Blaugust also carried additional emotional weight because many participants were writing in memory of Belghast. That gave the event a sense of continuity that went well beyond a posting challenge.
Daily Blogroll weathered Blaugust reasonably well as a digest, but the month also exposed its structural limits.
When nearly everybody is publishing frequently, editorial selection becomes much harder. A digest can no longer solve the problem simply by choosing the “best” posts. Readers may legitimately prefer very different subsets of an equally good collection.
That realization eventually pushed the project away from pure editorial curation and toward recommendation.
The recommendation problem was harder than the summarization problem
Summarizing posts turned out to be relatively straightforward.
The difficult question was:
Who wants to read this?
At first, the obvious solution seemed to be categorization. Assign each post some labels, let readers express interest or disinterest in those labels, and use the result as a lightweight recommendation system.
This immediately became a taxonomy problem.
A naive taxonomy grows without bound.
A post about Final Fantasy can be Gaming, RPG, JRPG, Final Fantasy, Square Enix, PlayStation, Console Gaming, Narrative Games, Retro Gaming, and perhaps several other things depending on what it actually discusses.
That is excellent metadata and terrible preference design.
The project gradually arrived at a much stricter principle:
A category should exist only when knowing that category materially improves the prediction that a reader will want the post.
That sounds obvious. In practice, it eliminated a surprising number of plausible labels.
“RPG” eventually failed the test. It usually duplicated game-genre metadata.
Generic “Gaming” was almost useless in a corpus already dominated by gaming blogs.
“Indie Games” only became useful once it was narrowly defined around indie discovery and the indie ecosystem, rather than being inherited automatically by every post about an independently developed game.
“Retro Gaming” worked only after it stopped meaning “an old game was mentioned.” It became a description of active engagement with older games, preservation, historical design, emulation, translation, or retrospective play.
“GameDev” survived because “I want to read about people making games” is genuinely different from “I want to read about games.”
The same distinction repeatedly appeared elsewhere.
A Valheim post did not automatically qualify as Survival/Crafting merely because Valheim belongs to that genre. A post about building, resource progression, automation, or surviving a new biome might qualify. A post about a patch or cross-play might not.
An HTML post was not automatically Open Web. A post about RSS, publishing independence, self-hosting, interoperable formats, or reader control probably was.
An AI post was not automatically Technology. Sometimes AI was a programming tool. Sometimes it was a cultural subject, a security problem, a publishing problem, or a regulatory question.
The goal became minimal predictive classification rather than exhaustive description.
That was probably the project’s most important conceptual result.
Zero categories turned out to be a feature
One of the stranger discoveries was that a good classifier must be comfortable returning nothing.
A post could be perfectly worthwhile and belong to none of the permanent recommendation categories.
A review of a particular game might need only the game title, franchise, genre, and platform metadata.
A post about a film, a book, a weekend trip, or a peculiar design decision might be best represented by its summary.
Trying to force every post into a category made the system worse.
This was especially noticeable once the project separated several different kinds of metadata:
- post-interest categories;
- game titles and franchises;
- game genres;
- platforms;
- temporary topics and events.
That separation prevented the permanent taxonomy from becoming a dumping ground.
Blaugust, Gamescom, Steam Next Fest, a particular expansion launch, or a current controversy can be highly useful discovery signals without becoming permanent settings that a reader must manage forever.
That distinction between durable preference and temporary topic proved extremely useful.
The controlled vocabulary eventually got small
After months of testing against real posts, the category list became much smaller than the early drafts.
The stable set was roughly:
- MMORPG
- Retro Gaming
- Cozy Games
- Tabletop
- Survival/Crafting
- Indie Games
- Game Development
- Blogging
- Open Web
- AI
- Technology
- Security & Privacy
This is not a taxonomy of everything people write about.
That is precisely why it works better.
Books, music, films, travel, family life, personal reflection, retirement, and assorted cultural material usually fell under Blogging when a broad preference signal was useful at all.
Many individual game reviews received no category.
Political and social commentary was initially given its own category, but it proved too broad to be consistently predictive and was eventually better handled through summaries and topical information.
The exercise became less about finding the perfect label and more about avoiding labels that merely restated the text.
The promotional hashtags were a separate problem
Another useful distinction emerged almost accidentally.
Daily posts also needed promotional hashtags.
At first it was tempting to use the same taxonomy for both recommendation and promotion. That turned out to be wrong.
A promotional hashtag answers:
What might help somebody discover today’s digest?
A recommendation category answers:
What stable preference could help determine whether this particular reader wants this particular post?
Those are not the same question.
A one-day digest might reasonably use #PuzzleGames, #CRPG, or a specific game hashtag even if none of those deserves a permanent preference switch.
Conversely, a category such as Open Web might be extremely useful for recommendation despite not always being the strongest promotional tag.
Separating those two jobs made both systems cleaner.
What worked
The strongest part of Daily Blogroll was not the automation. It was the source selection.
A carefully chosen set of personal blogs produced a feed with much more texture than a general gaming-news or technology feed. Writers revisited games years later, documented long-running hobbies, changed their minds, returned to abandoned projects, wrote about family and work, and occasionally disappeared before turning up again.
That continuity matters.
Traditional content systems are optimized around individual pieces. Blogs are often more interesting as accumulated lives.
Daily Blogroll also demonstrated that concise summaries can make a large blogroll approachable without replacing the original writing. A good summary gave enough information to decide whether to click while leaving the actual argument, anecdotes, voice, and detail with the author.
The system worked best when it acted as a map.
What did not work
The project never fully escaped the economics of scale.
More blogs meant more API calls, more summaries, more classification, more processing, and eventually more recommendation complexity.
There was also an inherent tension in using an LLM to support a project centered on independent human writing.
That tension was not hidden. The summaries were machine-generated, and the project was explicit about that. Still, any system that reduces essays to one-line descriptions risks shifting attention from authors toward the layer that describes them.
There were also classification failures of the ordinary kind.
Models like to classify things.
Given twelve available labels, they will often find reasons to use six unless instructed not to. Much of the later work on Daily Blogroll involved teaching the system that restraint was desirable.
Incidental references had to stop triggering categories.
A game’s genre had to stop automatically becoming the post’s subject.
An author’s usual interests had to stop leaking into classification of the current post.
The classifier had to learn that “none” was a valid answer.
That is not glamorous work, but it is where most recommendation systems either improve or become noisy.
The deeper lesson was about recommendation systems
Daily Blogroll started as a blogging project and ended up becoming a small experiment in recommender-system design.
The usual instinct is to gather more information.
More tags. More categories. More user preferences. More behavioral data. More inferred relationships.
The experiment repeatedly suggested the opposite.
Useful recommendation may depend less on describing everything and more on identifying a handful of distinctions that actually change decisions.
If a reader says:
- show me more MMORPG posts;
- show me less AI;
- I like tabletop;
- I do not care about security and privacy;
- I am interested in retro gaming;
those preferences can move substantial parts of the feed in useful directions.
Asking whether someone likes RPGs, PlayStation games, narrative games, indies, action games, puzzle games, strategy games, and dozens of other overlapping concepts may produce more data while making the system less understandable.
The best taxonomy was not the most accurate description of the corpus.
It was the smallest vocabulary that helped readers avoid things they did not want and find things they did.
That is a very different optimization target.
And then it ended
A year is long enough for an experiment like this.
Daily Blogroll proved that there is a substantial, active network of personal blogs worth following. It showed that LLM-generated summaries can help navigate that network without needing to replace the underlying writing. It exposed the limits of hand curation as the source pool grows. And it produced a surprisingly durable set of lessons about classification, metadata, and recommendation.
It also became work.
That matters.
Projects sometimes deserve to end not because they failed, but because they answered the question that made them interesting.
Daily Blogroll answered several.
There are still good blogs.
They are still difficult to discover.
Blaugust remains one of the better mechanisms for finding people who genuinely enjoy maintaining them.
A small amount of machine assistance can make a large blogroll much easier to navigate.
And the hardest part of recommendation is not understanding what a piece of writing contains.
It is deciding which parts of that understanding are actually useful to another person.
After a year, that seems like enough of an answer.


Leave a Reply